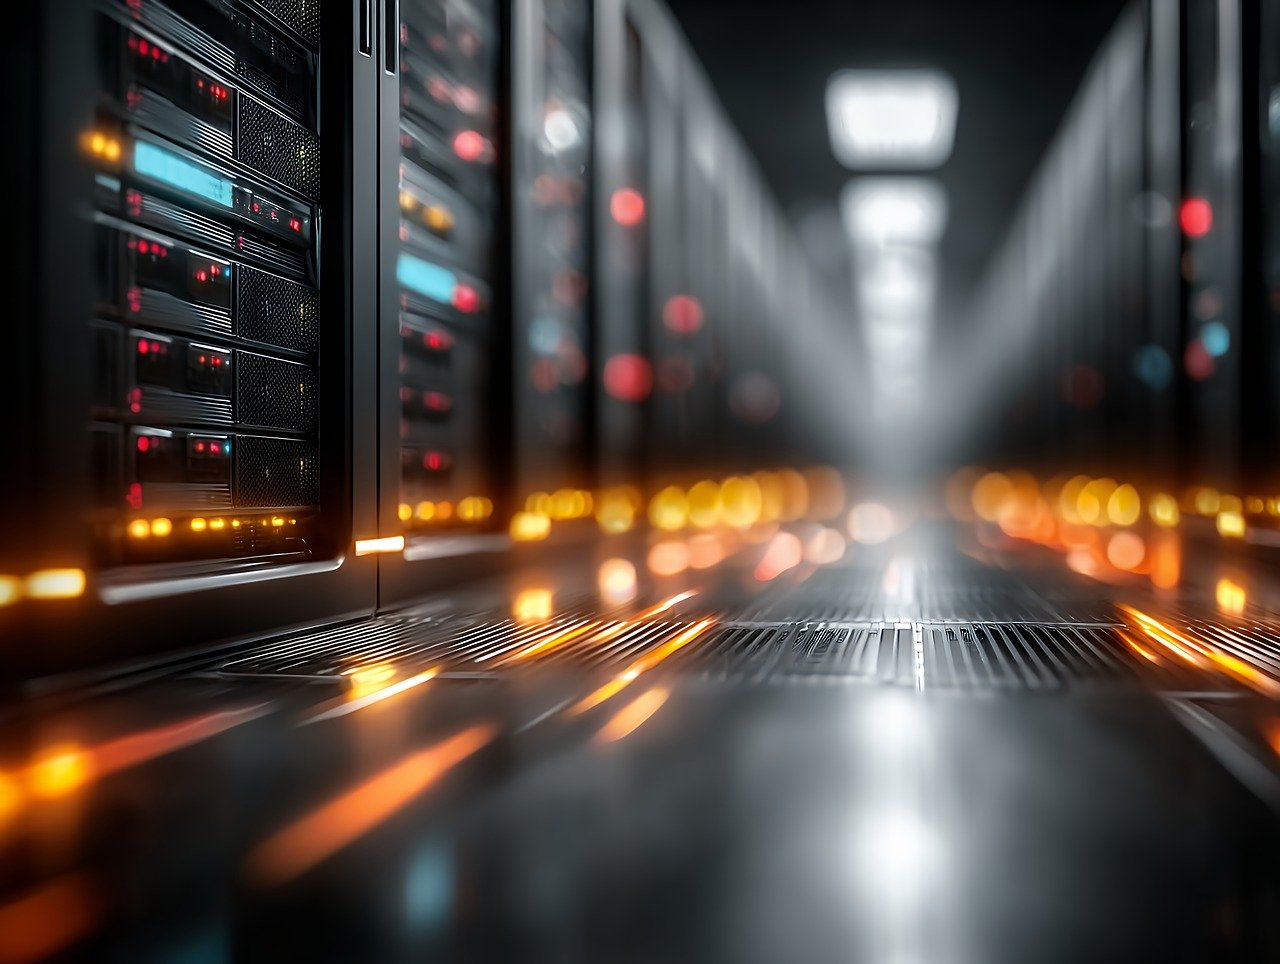

Outage stories usually get told after the disaster — a company goes dark, customers panic on social media, and the postmortem blog post follows weeks later. But some of the most instructive stories are the near-misses: the businesses that came within minutes of a catastrophic outage and walked away untouched, simply because of infrastructure decisions made long before anything went wrong. If you want to understand how businesses avoid major outages, these near-miss stories teach more than any theoretical checklist.
Why Near-Misses Matter More Than Success Stories
Every company wants to talk about growth and wins. Almost none want to talk about the afternoon their primary data center lost power, or the night a fiber cut took out their upstream provider. But these are exactly the moments that reveal whether infrastructure decisions were sound. The businesses below all had one thing in common: they had already built in redundancy before they needed it.
Case 1: The E-Commerce Retailer That Didn’t Notice a Power Failure
During a regional grid failure affecting an entire industrial park, one mid-sized online retailer kept processing orders without interruption. Their hosting environment ran on dual power feeds with automatic UPS and generator failover — meaning the outage never reached their servers at all. Customers never knew anything had happened. This is one of the clearest examples of how businesses avoid major outages: by making the failure invisible before it ever becomes a crisis.
Case 2: The SaaS Company That Survived a Network Provider Collapse
When a major upstream network provider suffered a multi-hour regional outage, dozens of companies hosted through single-carrier setups went dark. One SaaS company avoided the entire event because their provider used multi-carrier BGP routing — when one path failed, traffic simply rerouted through another upstream provider automatically. Their support team read about the outage on Twitter; their own dashboards showed nothing but green.
Case 3: The Agency That Recovered From a Failed Drive in Minutes
A digital agency managing dozens of client websites discovered a failing disk during a routine performance check. Because their hosting used RAID-protected storage with redundant drives, the failing disk was swapped without a single site going offline. Clients never filed a single support ticket. This kind of quiet resilience — powered by infrastructure like VyomCloud’s dedicated server plans — is what separates businesses that avoid major outages from those that experience them repeatedly.
Case 4: The Fintech Startup That Weathered a DDoS Attempt
A fintech startup became the target of a volumetric DDoS attack during a product launch — exactly the kind of event that can take an unprotected server offline for hours. Because their infrastructure included active DDoS protection, malicious traffic was filtered before it reached their application servers. Legitimate users experienced no slowdown at all.
Case 5: The Gaming Platform That Survived a Cooling System Failure
A cooling unit malfunction in a data center hosting a real-time multiplayer gaming platform could have caused thermal shutdowns across an entire rack. Redundant cooling infrastructure kicked in automatically, maintaining safe operating temperatures while the faulty unit was serviced. Players in an active match never experienced lag or disconnects.
The Common Thread
None of these businesses got lucky. They made infrastructure decisions — redundant power, multi-carrier networking, RAID storage, DDoS mitigation, and redundant cooling — long before any incident occurred. That’s the real answer to how businesses avoid major outages: not reactive fixes after a crisis, but proactive architecture that assumes failure will eventually happen.
What You Can Learn From These Stories
-
Redundancy has to be built in before the event, not after.
-
Single points of failure are invisible until they fail — audit every layer, not just the obvious ones.
-
DDoS protection isn’t optional for any business with public-facing infrastructure.
-
The businesses with the best outage stories are the ones with nothing to tell.
The Bottom Line
The most reassuring outage stories are the ones that never had to be told publicly — because nothing visible happened. That invisibility is the whole point, and it’s exactly what separates companies that understand how businesses avoid major outages from those learning the hard way.
Frequently Asked Questions
1. What’s the single most common cause of business outages? Single points of failure — one power source, one network path, or one disk — are the most common root cause across hardware, network, and infrastructure outages.
2. Can small businesses realistically afford this level of redundancy? Yes. Scalable redundant infrastructure is available across VPS and dedicated hosting tiers, not just enterprise-only plans.
3. How quickly does automatic failover typically happen? Well-configured failover for power and network redundancy typically occurs within seconds, often before users notice any disruption.
4. Does redundancy protect against DDoS attacks too? Redundancy protects against hardware and network failures; DDoS protection is a separate, complementary layer that filters malicious traffic specifically.
5. How do I know if my current provider has multi-carrier networking? Ask directly how many upstream network providers they use and what happens automatically if one fails.
6. Is it worth switching providers just for better redundancy? If your current provider can’t clearly explain their power, network, and storage redundancy, it’s worth evaluating alternatives before an outage forces the decision.
inesses That Survived a Major Outage Because of One Design Choice
Outage stories usually get told after the disaster — a company goes dark, customers panic on social media, and the postmortem blog post follows weeks later. But some of the most instructive stories are the near-misses: the businesses that came within minutes of a catastrophic outage and walked away untouched, simply because of infrastructure decisions made long before anything went wrong. If you want to understand how businesses avoid major outages, these near-miss stories teach more than any theoretical checklist.
Why Near-Misses Matter More Than Success Stories
Every company wants to talk about growth and wins. Almost none want to talk about the afternoon their primary data center lost power, or the night a fiber cut took out their upstream provider. But these are exactly the moments that reveal whether infrastructure decisions were sound. The businesses below all had one thing in common: they had already built in redundancy before they needed it.
Case 1: The E-Commerce Retailer That Didn’t Notice a Power Failure
During a regional grid failure affecting an entire industrial park, one mid-sized online retailer kept processing orders without interruption. Their hosting environment ran on dual power feeds with automatic UPS and generator failover — meaning the outage never reached their servers at all. Customers never knew anything had happened. This is one of the clearest examples of how businesses avoid major outages: by making the failure invisible before it ever becomes a crisis.
Case 2: The SaaS Company That Survived a Network Provider Collapse
When a major upstream network provider suffered a multi-hour regional outage, dozens of companies hosted through single-carrier setups went dark. One SaaS company avoided the entire event because their provider used multi-carrier BGP routing — when one path failed, traffic simply rerouted through another upstream provider automatically. Their support team read about the outage on Twitter; their own dashboards showed nothing but green.
Case 3: The Agency That Recovered From a Failed Drive in Minutes
A digital agency managing dozens of client websites discovered a failing disk during a routine performance check. Because their hosting used RAID-protected storage with redundant drives, the failing disk was swapped without a single site going offline. Clients never filed a single support ticket. This kind of quiet resilience — powered by infrastructure like VyomCloud’s dedicated server plans — is what separates businesses that avoid major outages from those that experience them repeatedly.
Case 4: The Fintech Startup That Weathered a DDoS Attempt
A fintech startup became the target of a volumetric DDoS attack during a product launch — exactly the kind of event that can take an unprotected server offline for hours. Because their infrastructure included active DDoS protection, malicious traffic was filtered before it reached their application servers. Legitimate users experienced no slowdown at all.
Case 5: The Gaming Platform That Survived a Cooling System Failure
A cooling unit malfunction in a data center hosting a real-time multiplayer gaming platform could have caused thermal shutdowns across an entire rack. Redundant cooling infrastructure kicked in automatically, maintaining safe operating temperatures while the faulty unit was serviced. Players in an active match never experienced lag or disconnects.
The Common Thread
None of these businesses got lucky. They made infrastructure decisions — redundant power, multi-carrier networking, RAID storage, DDoS mitigation, and redundant cooling — long before any incident occurred. That’s the real answer to how businesses avoid major outages: not reactive fixes after a crisis, but proactive architecture that assumes failure will eventually happen.
What You Can Learn From These Stories
- Redundancy has to be built in before the event, not after.
- Single points of failure are invisible until they fail — audit every layer, not just the obvious ones.
- DDoS protection isn’t optional for any business with public-facing infrastructure.
- The businesses with the best outage stories are the ones with nothing to tell.
The Bottom Line
The most reassuring outage stories are the ones that never had to be told publicly — because nothing visible happened. That invisibility is the whole point, and it’s exactly what separates companies that understand how businesses avoid major outages from those learning the hard way.
Frequently Asked Questions
- What’s the single most common cause of business outages? Single points of failure — one power source, one network path, or one disk — are the most common root cause across hardware, network, and infrastructure outages.
- Can small businesses realistically afford this level of redundancy? Yes. Scalable redundant infrastructure is available across VPS and dedicated hosting tiers, not just enterprise-only plans.
- How quickly does automatic failover typically happen? Well-configured failover for power and network redundancy typically occurs within seconds, often before users notice any disruption.
- Does redundancy protect against DDoS attacks too? Redundancy protects against hardware and network failures; DDoS protection is a separate, complementary layer that filters malicious traffic specifically.
- How do I know if my current provider has multi-carrier networking? Ask directly how many upstream network providers they use and what happens automatically if one fails.
- Is it worth switching providers just for better redundancy? If your current provider can’t clearly explain their power, network, and storage redundancy, it’s worth evaluating alternatives before an outage forces the decision.